AI SoftwareCorporation

AI Automation & MLAI Automation & Machine Learning

Take the rekeying and guesswork out of everyday operations

We turn documents into validated data, automate multi-⁠step processes and build forecasting models on your own history.

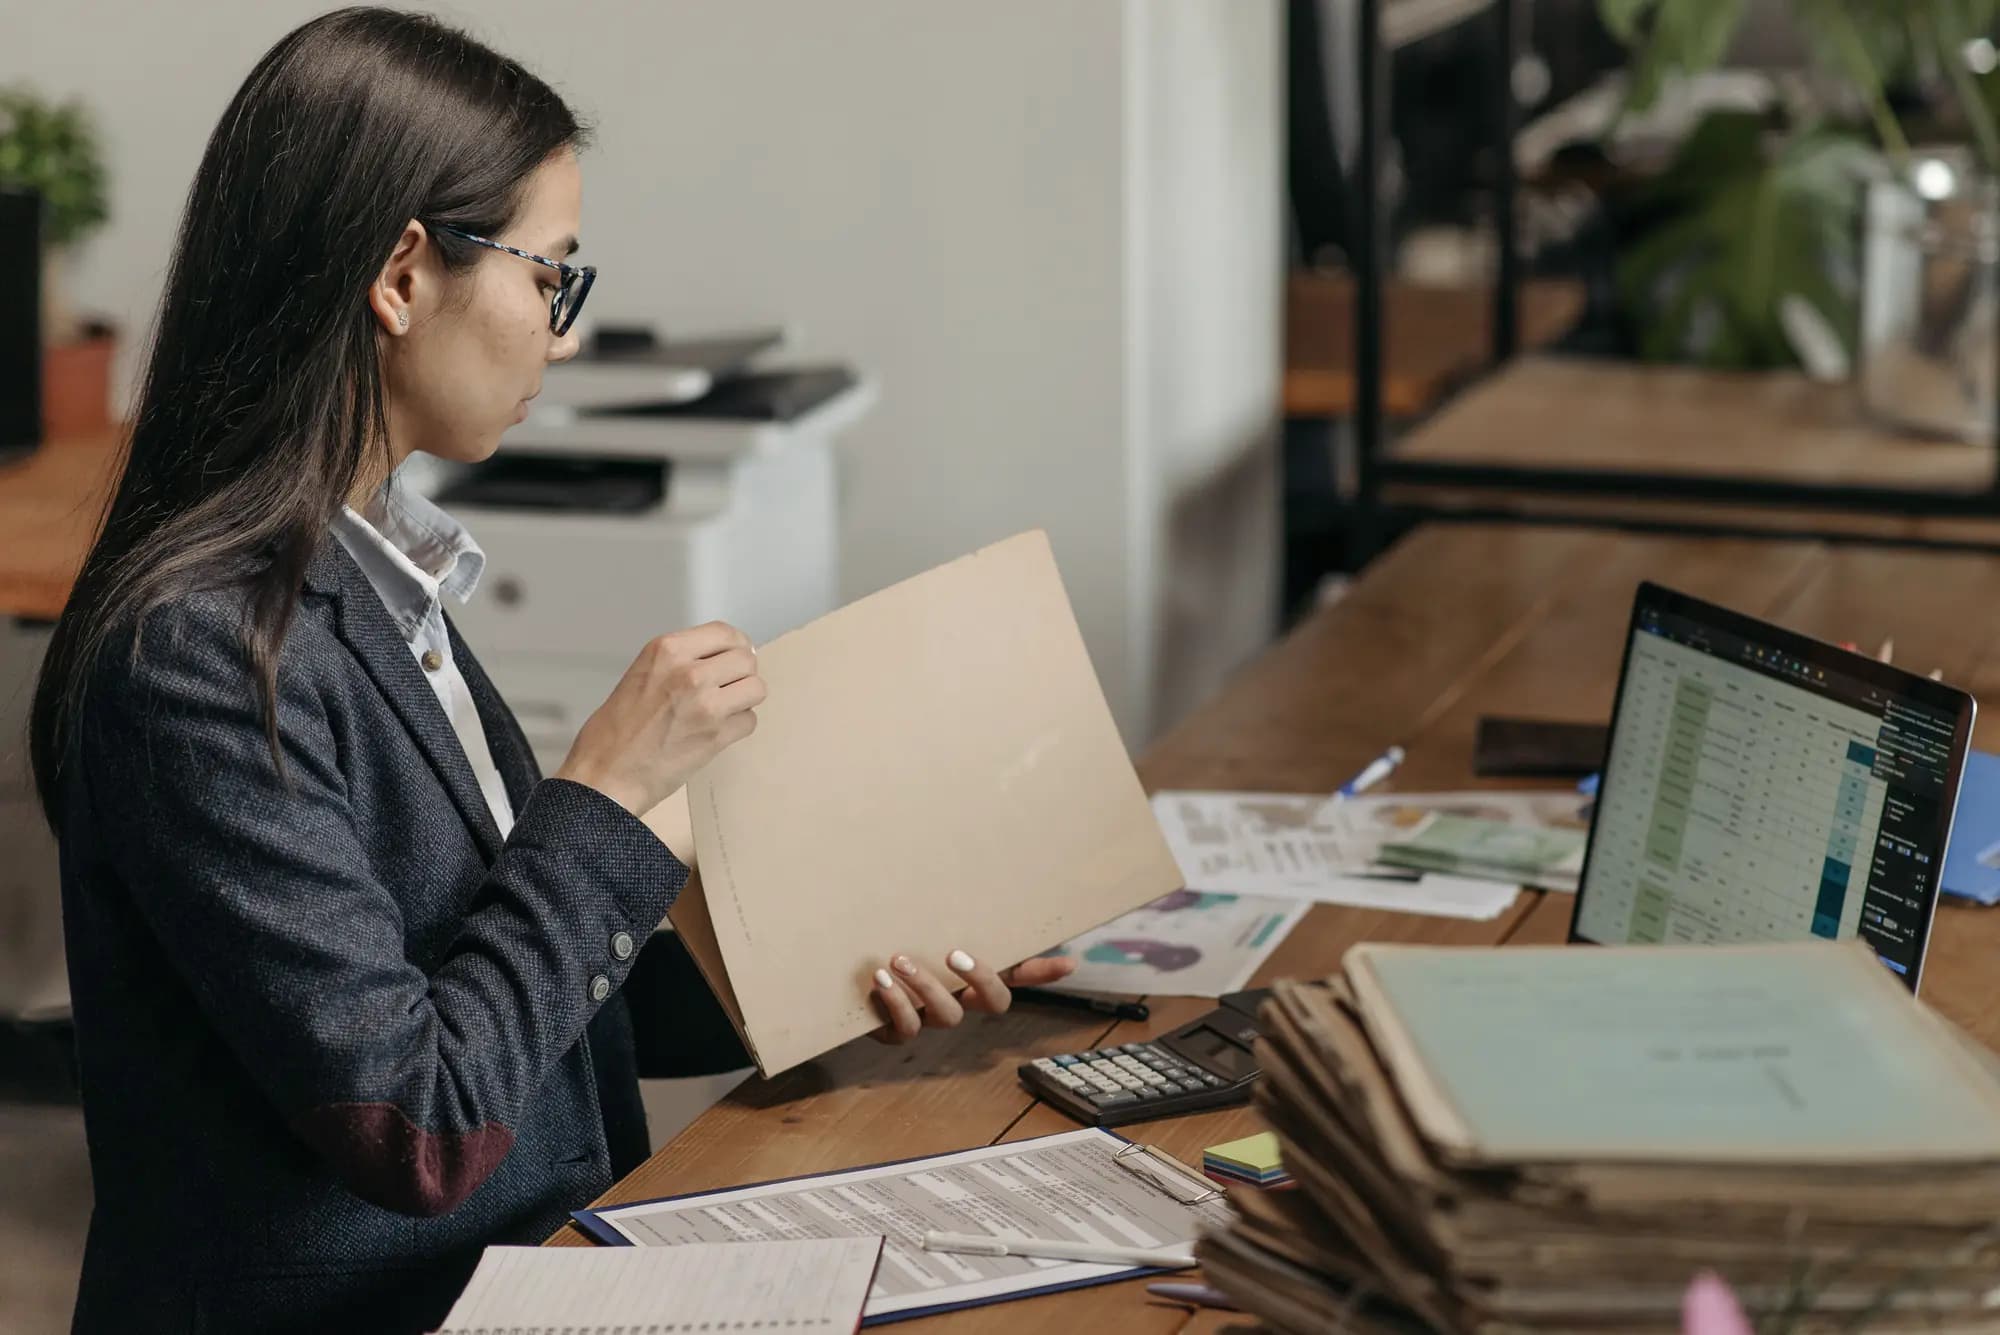
A woman at an office desk works through a folder, with a spreadsheet open on her laptop, a calculator and a tall stack of paper files beside her.

Outcomes

Less rekeying, earlier warnings

  • Reviewers see only the uncertain fields

    Documents become validated records without rekeying. Low-⁠confidence fields reach a reviewer next to the source, and each correction feeds back into testing and retraining.

  • Processes that run end to end

    Work moves between systems without inbox handoffs or rekeying. Every step has retries, deadlines and an audit trail, and anything that needs a person lands in a clear queue.

  • Earlier warning, fewer surprises

    Forecasts and anomaly alerts give planners and operations teams time to act, with uncertainty ranges shown instead of a single confident number.

  • Model decay caught early

    Drift monitoring spots when changing data starts to erode accuracy, and retraining runs through a tested pipeline that compares each new model with the current one before it ships.

Capabilities

From document intake to forecasts in production

Some projects start with the paperwork, others with a forecast. Either way, data pipelines, monitoring and cost tracking arrive with the first release rather than as a later phase.

Intelligent document processing

We turn invoices, claims, forms and contracts into validated data with OCR, layout analysis and language models, and link every value to where it appears in the source.

  • Classifying and splitting mixed document batches
  • Fields and tables extracted across varied layouts
  • Checks against business rules and reference data
  • Low-⁠confidence fields routed to a reviewer

Multi-⁠step process automation

We map the process, automate the predictable steps with rules and system integrations, and add a model only where inputs vary too much for rules to handle.

  • Durable workflows with retries, timers and rollback steps
  • APIs and events first, screen automation last
  • Exception queues with owners and deadlines
  • An audit trail for every automated step

Forecasting and predictive models

Models trained on your history to forecast demand and workload, score risk and spot anomalies, each benchmarked against a simple baseline before anyone relies on it.

  • Demand and workload forecasts with uncertainty ranges
  • Risk, churn and fraud classification
  • Anomaly detection on transactions, sensors and metrics
  • Reason codes that explain each prediction

Data engineering foundations

Models are only as reliable as their inputs. We build the pipelines, quality checks and storage layers that feed them as tested, version-⁠controlled code.

  • Batch and streaming ingestion, including change data capture
  • Quality tests and freshness alerts on every pipeline
  • Warehouse or lakehouse models with lineage
  • Shared feature definitions for training and serving

MLOps and model monitoring

Models ship like any other production software: versioned, tested, deployed through a pipeline and watched once they are running.

  • Experiment tracking and a versioned model registry
  • Batch scoring or real-⁠time serving behind an API
  • Data drift and prediction drift monitoring
  • Retraining with evaluation gates and rollback

Controls, privacy and running cost

Automated decisions stay within limits you set, sensitive data stays in your environment wherever possible, and the cost of each document or prediction is tracked from the first release.

  • Confidence thresholds and limits on automated decisions
  • Bias checks where predictions affect people
  • Processing in your cloud account, personal data masked
  • Cost per document, prediction or run tracked

Approach

Measure first, then automate

  1. Step 1: Map the process and the data

    We watch real cases move through the process, alongside the staff who handle them, and check what data exists, who owns it and whether it can be trusted.

    Activities

    • Shadow the team on routine cases and exceptions
    • Profile source data for gaps, errors and history
    • Decide per step: rules, a model or a person

    You receive

    • A process map with automation candidates ranked by value and risk
    • A data readiness report, including what to leave manual
  2. Step 2: Agree on the baseline and the bar

    First we measure how the current process performs, then agree on the accuracy and coverage a new approach must reach to be worth running.

    Activities

    • Label a representative sample with your experts
    • Measure current accuracy, effort and cost of errors
    • Set acceptance criteria and review thresholds

    You receive

    • A labeled evaluation set and baseline measurements
    • Written acceptance criteria
  3. Step 3: Build the data foundations

    Pipelines, quality checks and feature definitions come first, so models are trained and run on the same reliable data.

    Activities

    • Build ingestion and transformations as tested code
    • Add quality checks, lineage and freshness alerts

    You receive

    • Monitored production data pipelines
  4. Step 4: Prototype, then integrate

    Rules, classic models and language models compete on the same evaluation set. The approach that clears the bar is integrated with your systems of record, with review queues and fallbacks.

    Activities

    • Backtest models against the baseline and each other
    • Integrate through APIs, events or a workflow engine
    • Pilot with reviewers checking every output

    You receive

    • A production workflow or model service
    • Runbooks and model documentation
  5. Step 5: Monitor, retrain and extend

    In production we track accuracy, drift, exception rates and cost, retrain when the data shifts, and gate every new model version on the evaluation set.

    Activities

    • Review exceptions and reviewer corrections
    • Monitor drift and trigger retraining
    • Automate more only where results support it

    You receive

    • Regular accuracy, drift and cost reporting
    • A retraining pipeline with rollback

Deliverables and fit

Pipelines, models and monitoring you keep

What you receive

8 deliverables
  • Process and data assessment, including steps that should stay manual
  • Labeled evaluation set, baseline measurements and acceptance criteria
  • Data pipelines with quality tests, lineage and alerts
  • Production document processing or workflow automation, with a reviewer queue
  • Trained models with backtest results and model cards
  • MLOps setup: model registry, deployment pipeline and drift monitoring
  • Dashboards for accuracy, exceptions, drift and cost
  • Runbooks and handover sessions for your operations and data teams
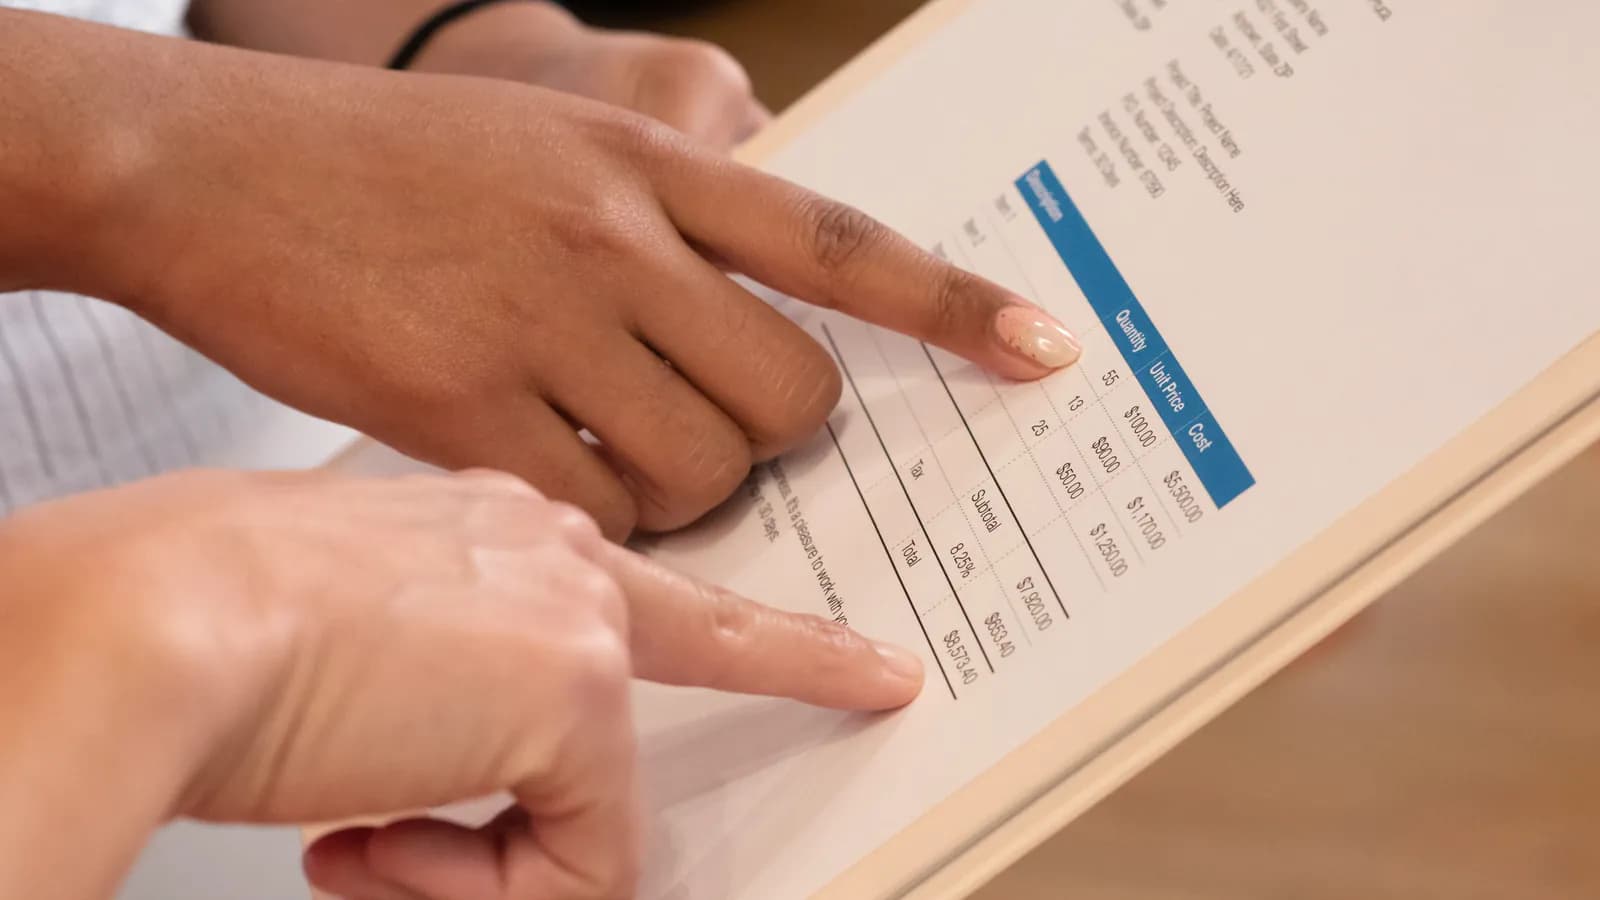
Two fingers point at line items on a printed invoice.
A low-⁠confidence line checked against its source

A good fit if

  • Your teams rekey data from documents, emails or portals into core systems
  • Work waits in inboxes and spreadsheets between one system and the next
  • Planning runs on spreadsheets and last year’s figures rather than forecasts
  • Fraud, errors or equipment faults are found only after the damage is done
  • A model worked in a notebook but never reached production, or has quietly degraded since
  • You suspect your data needs work before any model can rely on it

Engagement models

Automate one process, or work through a backlog

The models that usually suit this service. You can switch as the work changes.

  • Project delivery

    One process automated end to end, measured against the baseline agreed at the start.

  • Dedicated team

    A backlog of processes to automate in turn, with the data context carried from one to the next.

  • Managed support

    Models and pipelines in production that need drift checks, retraining and upgrades.

Technology

Document, workflow and ML tools

Listed so you can check the fit with your stack. None of them implies a partnership or certification.

Tools and platforms

  • Azure AI Document Intelligence
  • Amazon Textract
  • dbt
  • Snowflake
  • Databricks
  • Apache Kafka
  • Apache Airflow
  • Temporal
  • Camunda
  • MLflow
  • Evidently
  • scikit-learn
  • XGBoost
  • PyTorch

Illustrative scenario

Illustrative scenarioTurning emailed purchase orders into validated ERP entriesRead the scenarioHide the scenario
Illustrative scenario

Turning emailed purchase orders into validated ERP entries

An industrial parts distributor’s order desk, receiving purchase orders from many customers as PDFs, spreadsheets and plain email text.

Challenge
Every order is keyed into the ERP by hand. Layouts differ from customer to customer, many orders use the customer’s own part codes, and mistakes surface only when the wrong item ships.
Approach
  1. 1Map how orders arrive, which fields matter and which mistakes cost the most
  2. 2Extract order lines and match customer part codes to the catalog, learning from each reviewer correction
  3. 3Check prices, quantities and ship-⁠to details against the ERP before an order is created
  4. 4Send low-⁠confidence lines, and orders that break a customer’s usual pattern, to a review queue with the source highlighted
  5. 5Score each release against a labeled set of past orders, and track accuracy and cost per order in production
Outcome
The desk reviews exceptions instead of typing every line, each ERP order links back to its source document, and accuracy is tracked on live orders against the labeled baseline.

Services involved
Ask about a project like this

FAQ

Questions before you automate a process

Ask a question

Should we use rules, classic machine learning or a language model?

Whichever is simplest and meets the bar on your evaluation set. Rules suit stable, well-⁠defined logic. Classic models such as gradient-⁠boosted trees suit predictions from structured data and are cheap to run and easier to explain, while language models earn their place when inputs are free text or vary too much for rules. Most systems we build use a mix, and we tell you when a step should stay manual.

What if our data isn’t ready?

That is common, and better found early than after a model is built. Our assessment profiles the data a use case needs for completeness, accuracy, history and permission to use it, and sets out what to fix first. Often the first deliverable is a reliable pipeline, which also improves the reporting that depends on the same data.

How accurate will document extraction be on our documents?

That depends on your documents, so we measure it rather than promise it. We label a sample of your own documents, deliberately including poor scans and unusual layouts, and report accuracy per field before you decide to go to production. Confidence thresholds then decide what is processed automatically and what goes to a reviewer, and you can adjust them as results come in.

How do you keep models accurate after launch?

We monitor input data and prediction patterns continuously, and accuracy itself once real outcomes arrive, with alerts when any of them shift. Retraining runs through a pipeline that compares the new model with the current one on held-⁠out data, and the new model replaces the old only if it does at least as well on the measures you care about. Every version is registered, so rolling back is a deployment rather than a rebuild.

What happens to sensitive data in our documents and records?

Our practice is to process it in your own cloud account and region, mask or drop personal fields a step does not need, and apply your retention rules to source files, extracted data and logs. Access is limited to the people and services that need it, and every automated decision is logged. If a third-⁠party model or service is involved, its data terms are reviewed and agreed with you before any real record is sent.

Next step

Which process is worth automating first?

Describe the system, process or decision in front of you. Expect questions back, a sensible first step and a fitting engagement model.

First step
A conversation about the problem, your systems and constraints
You leave with
A view on whether we can help, and a sensible first step
Before any work
A written proposal covering scope, team, approach and terms
Commitment
None until you approve that proposal